


Overview
The dd utility remains one of the most versatile low-level data duplication and stream conversion tools in Linux environments. From provisioning mock test files and capturing raw disk images to evaluating storage subsystem write throughput, mastering its parameter flags is indispensable for any systems engineer. This hands-on tutorial walks through fundamental options including bs, count, status=progress, conv, and oflag through reproducible terminal workflows.
1. Core Syntax: Controlling Stream Targets (if, of) and Block Allocations (bs, count)
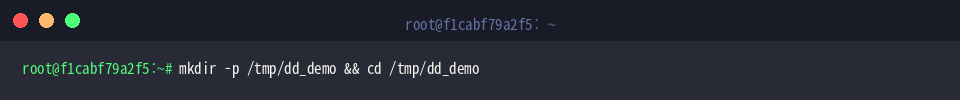
Isolate experimental operations inside a dedicated temporary workspace by running mkdir -p /tmp/dd_demo && cd /tmp/dd_demo.
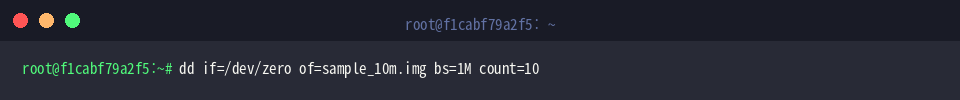
At its architectural core, dd copies data sequentially in discrete block-sized buffers between arbitrary endpoints. By reading zero-byte streams from /dev/zero, you can generate an empty 10MB test container named sample_10m.img via ten consecutive 1MB block write cycles.
⚙️ [Key Options]
if=FILE : Defines the input origin path, targeting either a regular file or a physical device node.of=FILE : Designates the destination file or target storage device receiving the stream.bs=BYTES : Configures the read/write buffer block size processed per cycle.count=N : Restricts execution to an exact total of input blocks copied before terminating.status=LEVEL : Toggles diagnostic outputs and throughput metrics across execution stages (e.g., progress).conv=CONVS : Applies data transformations or cache-flushing modes during processing (e.g., sync, fdatasync).
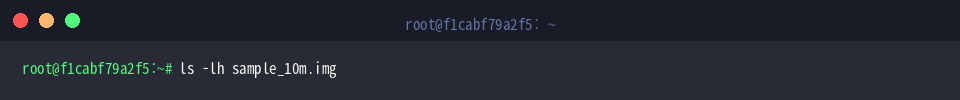
Verify the resulting dummy file’s allocated size and disk footprint by executing ls -lh sample_10m.img.
2. Live Transfer Feedback: Tracking Long-Running Tasks with status=progress
Re-enter the dedicated practice directory before initiating larger streaming operations by executing cd /tmp/dd_demo.
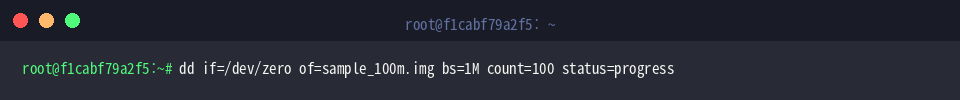
Because dd runs silently without outputting interim metrics by default, tracking progress on large file allocations or disk clones can be challenging. Supplying status=progress displays dynamic transfer rates, elapsed time, and total bytes written while producing a 100MB container named sample_100m.img.
Confirm that the payload has been accurately flushed to the filesystem by checking its metadata with ls -lh sample_100m.img.
3. Inline Stream Transformations: Practical Data Manipulation with conv
Return to the active working location with cd /tmp/dd_demo to explore inline stream processing.
Initialize a simple ASCII text file containing lowercase strings by running echo 'hello linux ubuntu dd command tutorial' > input.txt.
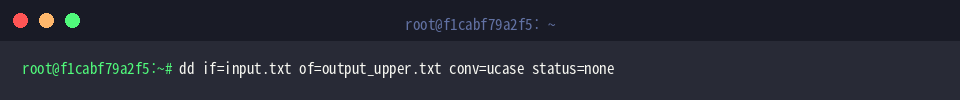
Beyond raw block cloning, dd supports instant data re-encoding and character case switching. Appending conv=ucase parses all lowercase characters into uppercase while piping the transformed output into output_upper.txt. Meanwhile, status=none mutes standard summary statistics to yield clean, script-friendly execution.
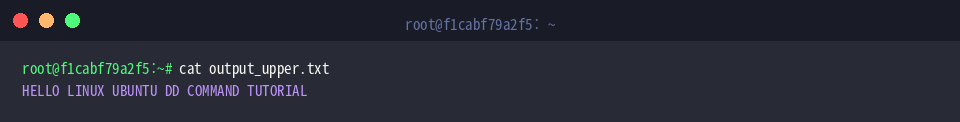
Print the transformed file contents using cat output_upper.txt to verify that character conversion was applied correctly.
4. Measuring True I/O Throughput: Bypassing Caches with oflag=direct
Navigate back to the designated test sandbox using cd /tmp/dd_demo to evaluate drive throughput.
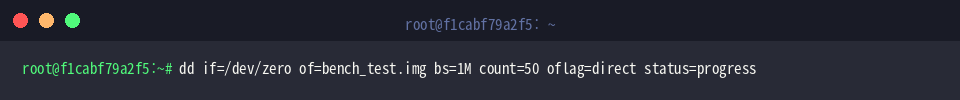
Standard storage operations rely heavily on kernel page cache buffering, which often distorts synthetic disk speed readings. Declaring oflag=direct bypasses volatile OS memory caches entirely, streaming 50MB of raw data directly onto underlying disk sectors. Combining this flag with status=progress offers an authentic assessment of unbuffered hardware write speeds.
Following benchmark completion, clean up the temporary staging directory and its contents by running rm -rf /tmp/dd_demo.
This walkthrough covered core flags, stream conversions, and cache-bypassing performance checks available in the Linux dd utility. Because dd operates with unconstrained low-level authority and overwrites destination targets without prompting, always verify destination arguments (of) diligently before hitting enter.